
Split a Batch PDF Into One File per Customer Without Code
By Anu Verma
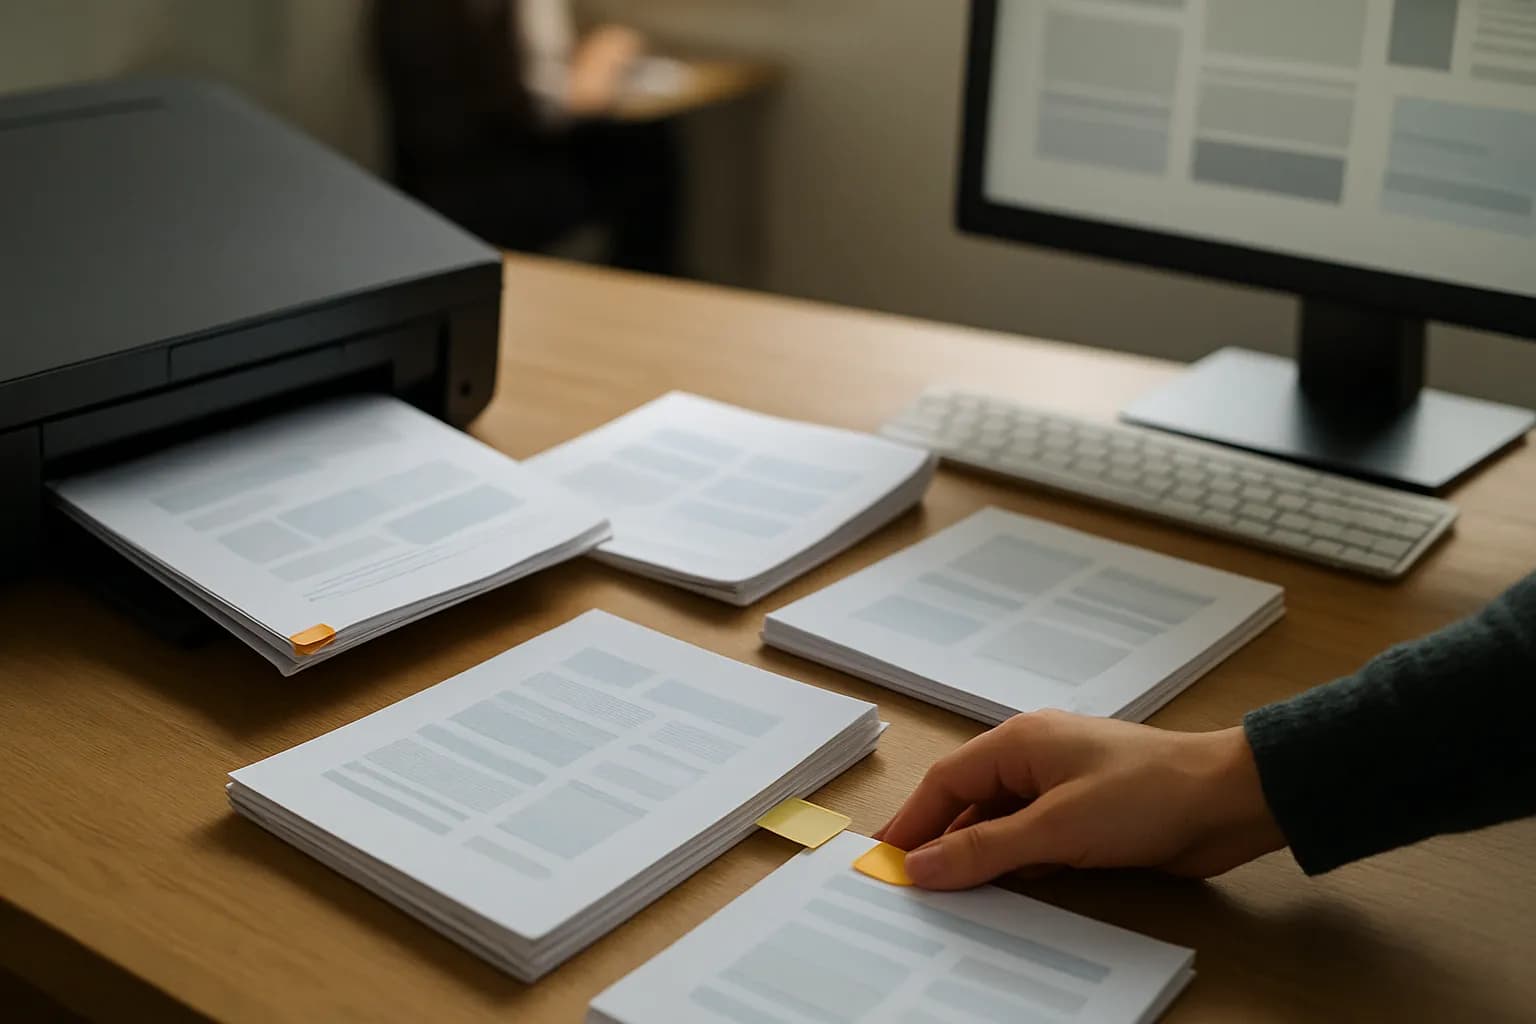
To split a batch PDF into one file per customer without coding, identify where each customer’s document starts, extract the page ranges, and check every output before sending it. Automate the split only when those boundaries are consistent and readable.
To split a batch PDF into one file per customer without coding, identify where each customer’s document starts, extract the page ranges, and check every output before sending it. Automate the split only when those boundaries are consistent and readable.
A reliable split starts at a document boundary
A customer name is not, by itself, a safe place to split a batch PDF. The useful boundary is the start of a new document, supported by a consistent feature such as a statement header, a form title, or a customer identifier in the same position. A name printed on a continuation page may identify its owner without starting a new document.
Open the PDF and look through several changes between customers. Note what marks the first page of each document and what appears on its continuation pages. Check whether attachments belong to the document before them or begin a separate record. A cover sheet, blank page, or shared notice also needs an explicit destination: exclude it, keep it with a particular customer, or hold it for review.
Use a stable customer identifier where possible. Names can be spelled differently, shared by different customers, or misread in a scan. If the batch has no dependable start marker, separating a multi customer PDF into individual documents is a page-by-page review task, even if a PDF tool makes extracting the pages quick.
A worked batch separates clear ranges from uncertain pages
A batch containing a cover sheet, customer statements, and attachments should be split by confirmed document starts, not by every appearance of a customer name. Imagine the cover sheet is followed by a statement with a clear customer identifier. Its next page has no identifier but plainly continues the statement. A new statement header then introduces another customer, followed by an attachment that refers to that statement. Later, a fresh statement header belongs to the earlier customer again.
The clear headers mark separate document ranges. Keep each continuation page with the statement it continues. The attachment needs a check: if its reference or surrounding pages establish which statement it belongs to, include it there. If not, hold that range out of the output rather than guessing. Exclude or file the cover sheet according to your workplace rules.
The returning customer exposes an important choice. If the request is one file per customer, combine that customer’s verified ranges after splitting. If the statements must remain separate records, keep separate files instead. A splitter cannot settle that business rule from the repeated name alone.
A page-range PDF tool is enough for an occasional batch
A PDF splitter with page-range extraction is the simplest no-code option when someone can identify the boundaries reliably. Review the source PDF, record the beginning and end of each customer document, and use the tool’s extract or split function to save those ranges. For a customer who appears in nonadjacent ranges, use a PDF combine function only after confirming that the documents should share a file.
Save the outputs in a restricted working folder, not the folder used to send files. Give each file a consistent name based on a verified customer identifier and the kind of document. Open the saved PDFs to check that extraction kept the pages in order and did not drop an attachment. Keep the original batch unchanged so you can resolve a disputed page assignment.
This manual method is often better than building an automation for irregular batches. It avoids teaching a workflow to guess at changing layouts. If files arrive from customers before you build the batch, collecting client files without sharing your folders addresses that separate intake problem.
Automatic splitting needs a review route for exceptions
To split a PDF by customer name automatically, use a no-code document processing tool to read the pages and a workflow tool to apply your boundary rules. For scanned pages, the document tool must first turn the page images into searchable text. Look for tools that can extract fields, identify document starts, and pass results to a workflow; check each vendor’s documentation and pricing page for the features available to you.
Set the workflow to start a range only when it finds the expected document marker and a usable customer identifier. End the range at the next confirmed start, then group verified ranges by identifier if the intended output is one file per customer. A missing marker, conflicting identifiers, unreadable scan, or attachment with uncertain ownership should create a review task rather than a customer file ready to send.
Test the rule on copies of representative batches, including awkward scans and returning customers. Compare each proposed range with the source PDF before allowing routine runs. An extracted name can help name a file, but it does not prove that every page in the file belongs to that customer.
Filenames and delivery require their own checks
A correctly split PDF can still reach the wrong person if its filename or delivery rule is wrong. Match the verified customer identifier in the document to your customer record before choosing a filename or recipient. Do not use a name read from an uncertain page as the sole lookup key. Where names repeat, use the identifier your workplace already relies on to distinguish records.
Keep extraction, review, and sending as separate stages. Put new files in a private review folder and move only approved outputs to the delivery folder. If you later use a folder-triggered workflow, remember that automatically emailing new files in a folder addresses sending, not whether a PDF was split correctly. Connecting the trigger to the unreviewed folder would remove your last chance to catch a mixed-customer file.
Check who can access the source, temporary files, review folder, and completed files. If a tool processes sensitive customer records outside your usual storage, confirm that its handling meets your workplace requirements before uploading a batch.
A final reconciliation catches missing and mixed pages
Before sending, account for every source page and inspect every customer output. Compare the batch with the saved files in page order. Each page should appear in the right customer file, be deliberately excluded under your rules, or remain in a review queue. Watch for pages duplicated during a merge as well as pages omitted during extraction.
Open the beginning and end of each output and check the transitions around attachments and returning customers. Then search or scan the remaining pages for another customer’s identifier. For a scanned PDF, inspect the page image too: searchable text can be wrong even when the page looks clear to a person. Verify that the filename matches the contents, and check the intended recipient separately from both.
Keep a brief record of reviewed exceptions and any corrections made to the split. If the same uncertainty recurs, change the boundary rule or keep that document type in manual review. The goal is not to remove every human check. It is to make clear which files can follow a repeatable rule and which need a decision before anyone receives them.
Sources consulted
- Microsoft Learn (learn.microsoft.com)
- Zapier (zapier.com)
Frequently asked questions
Can I split a multi customer PDF into separate files without special software?
Yes, if your existing PDF application can extract page ranges. Identify where each customer document begins and ends, save those ranges as separate PDFs, and open the results to verify them. If the application cannot combine nonadjacent ranges, keep those documents separate or use a PDF tool with a combine function.
Can a tool split a PDF by customer name automatically?
A no-code document processing tool may read customer identifiers and pass them to a workflow that groups pages, but a name alone is not a reliable boundary. The workflow also needs a consistent document-start marker. Send unreadable pages, conflicting identifiers, and uncertain attachments to manual review instead of sending the resulting files automatically.
What if the same customer appears more than once in the batch?
Treat each confirmed document start as a separate range first. If the required result is one file per customer, combine that customer’s verified ranges in the intended order. If the records must stay separate for filing or delivery, do not combine them merely because the customer identifier matches.
What should I check before sending the split PDFs?
Account for every page in the source, including covers and attachments. Open each output to check its first and last pages, page order, customer identifier, and filename. Resolve any page with uncertain ownership, then verify the recipient against your customer record rather than relying on the PDF filename.
Related guides
 Create Client Folders From New Airtable RecordsCreate a client folder and standard Drive subfolders from an Airtable record, then save their links so retries can reuse what already exists.
 Make a PDF Automatically From Each Google Form ResponseConnect Google Forms to a document template, fill blank answers safely, and save a PDF for each new response without code.
 Auto-File Email Attachments to SharePoint and Notify the Team (Power Automate)Build a Power Automate flow that files every Outlook attachment into the right SharePoint folder and posts a note in Teams, with no code.
Drafted with AI assistance and checked automatically before publishing. Tools and prices change; check the official source before you act.